How AI Models Are Actually Trained (Step by Step)
Artificial intelligence can feel almost magical from the outside. You type a question, upload an image, or give a voice command, and a model produces an answer in seconds. But behind that instant response is an enormous training process involving data, mathematics, computing power, experimentation, and repeated correction.
By Aidan Mays on September 17, 2026
Getty Images
Artificial intelligence can feel almost magical from the outside. You type a question, upload an image, or give a voice command, and a model produces an answer in seconds. But behind that instant response is an enormous training process involving data, mathematics, computing power, experimentation, and repeated correction.
The basic idea is simpler than it sounds. An AI model learns patterns from examples. During training, it is shown huge amounts of data and repeatedly asked to make predictions. When those predictions are wrong, the model is adjusted slightly. After enough repetitions, it becomes much better at producing useful outputs.
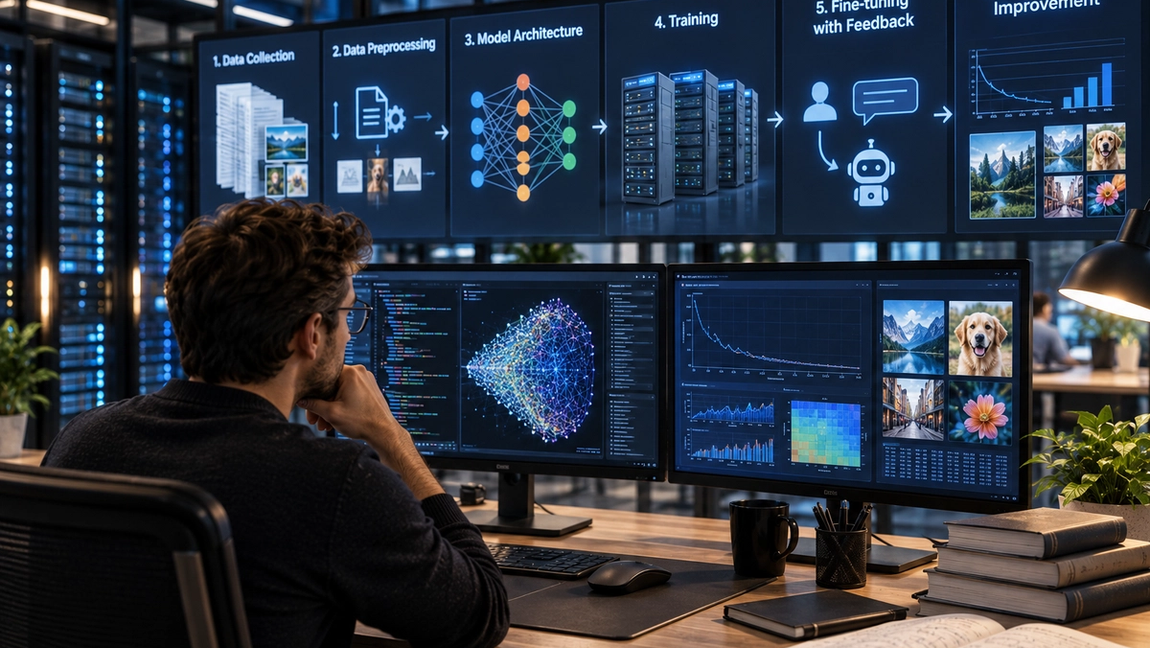
The exact process depends on the type of AI system, but modern language models generally follow a recognizable sequence.
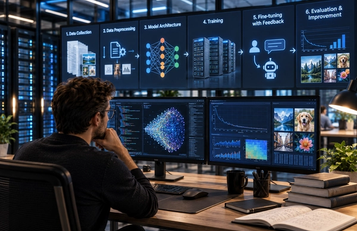
Step 1: Collect and prepare the training data
Training starts with data.
For a language model, this may include large collections of text such as books, articles, websites, code, reference material, and other written content. Image models require large collections of images and associated information. Speech models need audio, while multimodal systems may learn from combinations of text, images, audio, and video.
But raw data cannot simply be dumped into a model.
Training datasets usually go through extensive preparation. Duplicate material may be removed. Low-quality or corrupted files can be filtered out. Personally identifying or otherwise inappropriate information may be excluded according to the system’s policies and training goals.
The data also needs to be converted into a form computers can work with efficiently.
For language models, this means breaking text into smaller units called tokens. A token might represent a whole word, part of a word, punctuation, or another short sequence of characters.
The model does not initially understand those tokens the way humans understand language. It begins by treating them as numerical representations from which it gradually learns relationships.
Step 2: Give the model a structure
Before training starts, engineers choose the model’s architecture.
Many modern language models use a neural-network architecture called a transformer. A transformer is designed to identify relationships between pieces of information, including words that may appear far apart in a sentence or document.
The network contains a very large number of adjustable numerical values called parameters.
You can think of parameters as millions or billions of tiny settings inside the model. At the beginning of training, those settings do not encode much useful knowledge. The training process gradually adjusts them so that the model becomes better at recognizing patterns.
Larger models may contain billions or even hundreds of billions of parameters, although having more parameters does not automatically guarantee that a model will be better.
Architecture, data quality, training techniques, and computing resources all matter.
Step 3: Teach the model to predict what comes next
The central training exercise for many language models is surprisingly simple: predict the next token.
Imagine the training text contains the sentence, “The dog ran across the…”
The model might initially predict “window,” “street,” “moon,” or dozens of other possibilities. The actual next token might be “garden.”
The training system compares the model’s prediction with the correct answer and calculates how wrong it was.
That difference is represented through something called a loss function.
The goal of training is to reduce this loss. In other words, the model repeatedly makes predictions and gradually becomes less wrong.
This process happens across enormous quantities of text. Over time, the model begins learning grammar, writing styles, facts, relationships between concepts, programming patterns, common reasoning structures, and many other statistical patterns contained in the training data.
It is not memorizing a giant answer sheet. It is learning a complex probability system for predicting what information should come next.
Step 4: Adjust the model after every mistake
Once the model makes a prediction and the loss is calculated, the system needs to determine which parameters should change.
This happens through a process called backpropagation.
Backpropagation works backward through the neural network to determine how each parameter contributed to the mistake. An optimization algorithm then changes the parameters slightly in a direction expected to improve future predictions.
Those adjustments are usually tiny.
But they happen over and over again, potentially trillions of times across the entire training process.
Imagine trying to improve a golf swing by making millions of microscopic corrections based on where each shot lands. One adjustment does almost nothing. The accumulated effect of all of them can be enormous.
This repeated cycle of prediction, error measurement, and adjustment is the core of machine learning.
Step 5: Train at enormous scale
Training modern AI systems requires significant computing power.
Rather than using one normal computer, developers typically train large models across clusters containing many specialized chips such as GPUs or other AI accelerators.
Different machines process portions of the training workload simultaneously and coordinate their updates.
Training can continue for weeks or months depending on the size of the model, available hardware, dataset, and training strategy.
This stage is known as pretraining.
At the end of pretraining, a language model may be very good at predicting and generating text, but that does not necessarily make it a good assistant.
It might continue a conversation in strange ways, provide unhelpful answers, or fail to follow instructions consistently.
That is why additional training is usually required.
Step 6: Teach the model to follow instructions
After pretraining, developers can fine-tune the model using examples of desirable behavior.
Instead of simply asking the model to predict arbitrary internet text, trainers may provide examples containing a user request and an appropriate response.
For example, the model might receive a question asking for an explanation of photosynthesis followed by a clear, accurate answer.
Across many examples, the model begins learning what people mean when they ask it to summarize something, write an email, solve a problem, explain a concept, or follow a particular format.
This process is often called supervised fine-tuning.
Specialized models can also be fine-tuned for narrower tasks such as legal analysis, coding, medicine, translation, or customer service.
Step 7: Improve responses using human or automated feedback
Instruction-following alone does not guarantee that a model will consistently produce helpful responses.
Developers may therefore use additional feedback-based training.
Human reviewers can compare different model responses and indicate which one is better. Those preferences can then be used to train systems that help the model learn which responses people are more likely to find helpful, accurate, safe, or relevant.
Techniques such as reinforcement learning from human feedback, commonly called RLHF, became well known for this purpose.
Modern systems may also use feedback generated partly by other AI models, rule-based evaluation, automated tests, or combinations of several methods.
The central idea remains the same: generate possible behavior, evaluate it, and use the evaluation to improve future behavior.
Step 8: Test the model before release
Training is not complete when the model starts producing impressive answers.
Developers test it across large sets of tasks designed to measure capabilities and weaknesses.
These evaluations may examine reasoning, coding, mathematics, factual accuracy, language understanding, safety, bias, robustness, and many other areas.
Teams may also perform adversarial testing, sometimes called red teaming. Testers deliberately try to make the model fail, produce unsafe content, ignore instructions, or behave unpredictably.
Problems discovered during evaluation can lead to further fine-tuning, additional safeguards, changes to the training data, or even broader changes to the model.
Testing also continues after deployment because real users often discover behaviors that laboratory evaluations missed.
Training does not mean the model thinks like a person
The result of all this training can appear remarkably human.
A model can explain history, write code, imitate styles, summarize documents, or hold a conversation because it has learned extraordinarily complicated relationships between pieces of information.
But the mechanism is different from human learning.
An AI model does not sit down and read a book while consciously understanding each sentence. It processes numerical representations and adjusts parameters according to mathematical feedback.
What makes modern AI impressive is that a relatively simple training principle—predict, measure the mistake, adjust, repeat—can produce extremely sophisticated behavior when applied at enormous scale.
That is the basic story behind AI training.
First comes the data. Then the model predicts. Mathematics measures how wrong it was. The parameters are adjusted. The cycle happens again and again, followed by additional instruction training, feedback, and testing.
By the time you type a question into a finished AI system, that prediction-and-correction process has already happened an almost unimaginable number of times.